
What’s the question?
A fund tracking the S&P 500 is usually described as owning 500 companies. It does, but not in equal parts. The index is capitalisation weighted, so each member’s weight is its market value divided by the combined market value of every member: a company worth five trillion dollars carries a thousand times the weight of one worth five billion. The number of names describes the holdings; the spread of market value describes the risk.
Diversification depends on the second one, because a portfolio where four positions account for a quarter of the money behaves like a much smaller portfolio. The question is therefore not how many companies the index holds, but how many it effectively holds.
Two measures settle it. The combined weight of each rank band reports top-heaviness directly. The Herfindahl-Hirschman index (HHI), the sum of every member’s squared percentage weight, compresses the distribution into one number, and 10,000 divided by that number gives the effective number of members: the count of equally sized holdings that would produce the same concentration. An index of 500 identical companies would score an effective count of 500. Correlations, rather than weights, supply the effective count in an eigenvalue analysis of the index.
The approach
The measurement is one cross-section, taken on 21 August 2026, so every weight is priced on the same day. Members are addressed by entity id rather than by ticker: a symbol can move to another company after a rename, and a join on the string would then pair one company’s roster row with another company’s market value.
Each member’s market value is its total share count at the price of its principal listed line. That works wherever a company’s classes trade at comparable prices, the normal case: Alphabet’s two listed lines closed at $344.82 and $341.75 on the day. It fails when they do not, and the index holds one such member. Berkshire Hathaway’s Class A and Class B lines trade at a ratio of about 1,500 to 1, so no single per-share price values the combined count, and the company sits outside the sample.
- Pull the current S&P 500 roster and keep the entity id of each member.
- Pull each member’s market value and sector label over the week ending 21 August, in batches of 100 ids, and keep the last observation.
- Drop members whose share classes are not comparably priced. Members without a usable market value on the snapshot date also drop, which leaves 497 of the 504 roster entries.
- Convert market values into weights, sort from largest to smallest, and accumulate.
- Compute each rank band’s combined weight and the HHI with its effective member count, then repeat across the eleven sectors.
Code
import pandas as pd
import xfinlink as xfl

xfl.set_api_key("YOUR_API_KEY")  # free at https://xfinlink.com/signup

roster = xfl.index("sp500").dropna(subset=["entity_id"])
ids = sorted(set(roster["entity_id"].astype(int)))

caps = [xfl.metrics(entity_id=ids[i:i + 100], period_type="daily",
                    fields=["market_cap"], start="2026-08-14", end="2026-08-21")
        for i in range(0, len(ids), 100)]

df = pd.concat(caps, ignore_index=True).dropna(subset=["market_cap"])
df = df[df["market_cap"] > 0]
df = df.sort_values("period_end").groupby("entity_id", as_index=False).last()
df = df[~df["ticker"].isin({"BRK"})]  # classes not comparably priced
df = df.sort_values("market_cap", ascending=False).reset_index(drop=True)

df["weight"] = 100 * df["market_cap"] / df["market_cap"].sum()
df["cumulative"] = df["weight"].cumsum()

hhi = (df["weight"] ** 2).sum()
for k in (5, 10, 25, 50):
    print(f"largest {k:>3}      : {df['weight'].head(k).sum():.1f}%")
print(f"members         : {len(df)}")
print(f"HHI             : {hhi:.1f}")
print(f"effective count : {10000 / hhi:.1f}")
Full script with formatting and visualisation: sp500-index-weight-concentration-python.py
Output
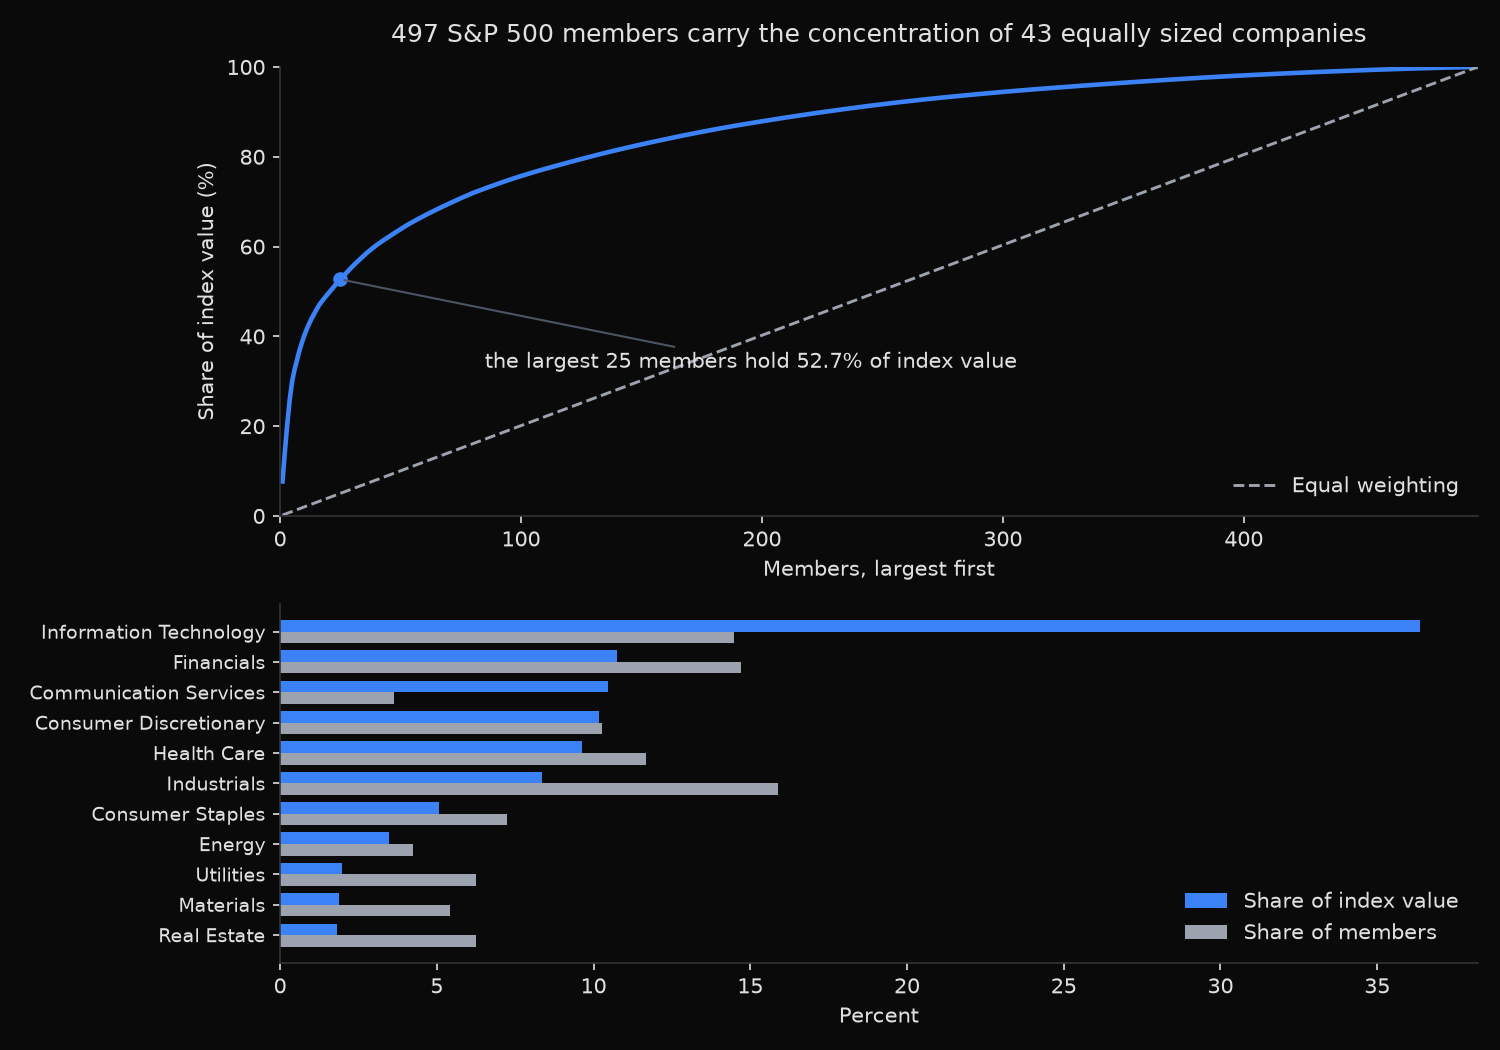
S&P 500 market value concentration, 2026-08-21
members on the roster       : 504
members in the sample       : 497
combined market value       : $67.65tn

rank band              combined weight
--------------------------------------
largest 1                         7.7%
largest 3                        20.6%
largest 5                        30.0%
largest 10                       40.1%
largest 25                       52.7%
largest 50                       63.9%
largest 100                      75.7%
smallest 248                      8.4%

Herfindahl-Hirschman index  :    230.3
effective number of members :     43.4
equal weight per member     :    0.201%
median member weight        :    0.066%
members above 5% of index   :        4
members above 1% of index   :       14

Five largest members
#  ticker      market value   weight  cumulative
1  NVDA               5.20t    7.68%       7.68%
2  AAPL               4.52t    6.68%      14.36%
3  GOOGL              4.22t    6.23%      20.60%
4  MSFT               3.59t    5.31%      25.90%
5  AMZN               2.79t    4.12%      30.02%

Sector split: share of members against share of index value
sector                      members  of members  of value
---------------------------------------------------------
Information Technology           72       14.5%     36.4%
Financials                       73       14.7%     10.8%
Communication Services           18        3.6%     10.5%
Consumer Discretionary           51       10.3%     10.2%
Health Care                      58       11.7%      9.6%
Industrials                      79       15.9%      8.4%
Consumer Staples                 36        7.2%      5.1%
Energy                           21        4.2%      3.5%
Utilities                        31        6.2%      2.0%
Materials                        27        5.4%      1.9%
Real Estate                      31        6.2%      1.8%
What this tells us
The five largest members hold 30.0% of the money and the largest 25 hold 52.7%, leaving 47.3% for the other 472 companies. The smallest 248 members, half the sample by count, hold 8.4% between them, barely more than NVIDIA alone at 7.7%.
The HHI of 230.3 puts the effective number of members at 43.4. A cap-weighted S&P 500 fund carries the concentration of a 43-stock portfolio while reporting close to 500 line items, and the median member holds 0.066% of assets, a third of what equal weighting would give it.
Sector concentration runs the same way. Information technology holds 14.5% of the members and 36.4% of the value; communication services turns 3.6% of the count into 10.5% of the value, four fifths of that in two companies. Industrials is the largest sector by member count at 79 names and carries 8.4% of the value; real estate’s 31 members add up to 1.8%. Counting companies by sector describes a balanced index; counting dollars describes a technology fund with a long tail.
So what?
Treat the 500 as a label and the 43 as the risk. A stress test, a factor decomposition or a benchmark comparison should run against the measured weights, not the roster count, since the two differ by a factor of eleven.
Mandate compliance is where this bites first. A portfolio limited to 5% in any single holding cannot replicate this index without going underweight in four places, and those four positions then decide most of the tracking error. Benchmark choice is the other place: equal weighting the same companies gives the median holding three times the weight it carries here, so an equal-weighted strategy judged against the cap-weighted index is scored on size and sector tilt more than on skill.
Rerun the measurement each quarter. The HHI moves with prices rather than only with membership changes, so the effective count drifts between rebalances and falls fastest when the largest members are performing best.
Built with xfinlink — free financial data API for Python.